Home ﹥ Hot News > Artificial Intelligence > Computing > XRM-SSD V24 / V24.5 One Primitive, 18 Applications — The Deterministic Scheduling Moat 2026-07-07
Links:https://www.datagravity.dev/p/the-ai-networking-stack
Github doc
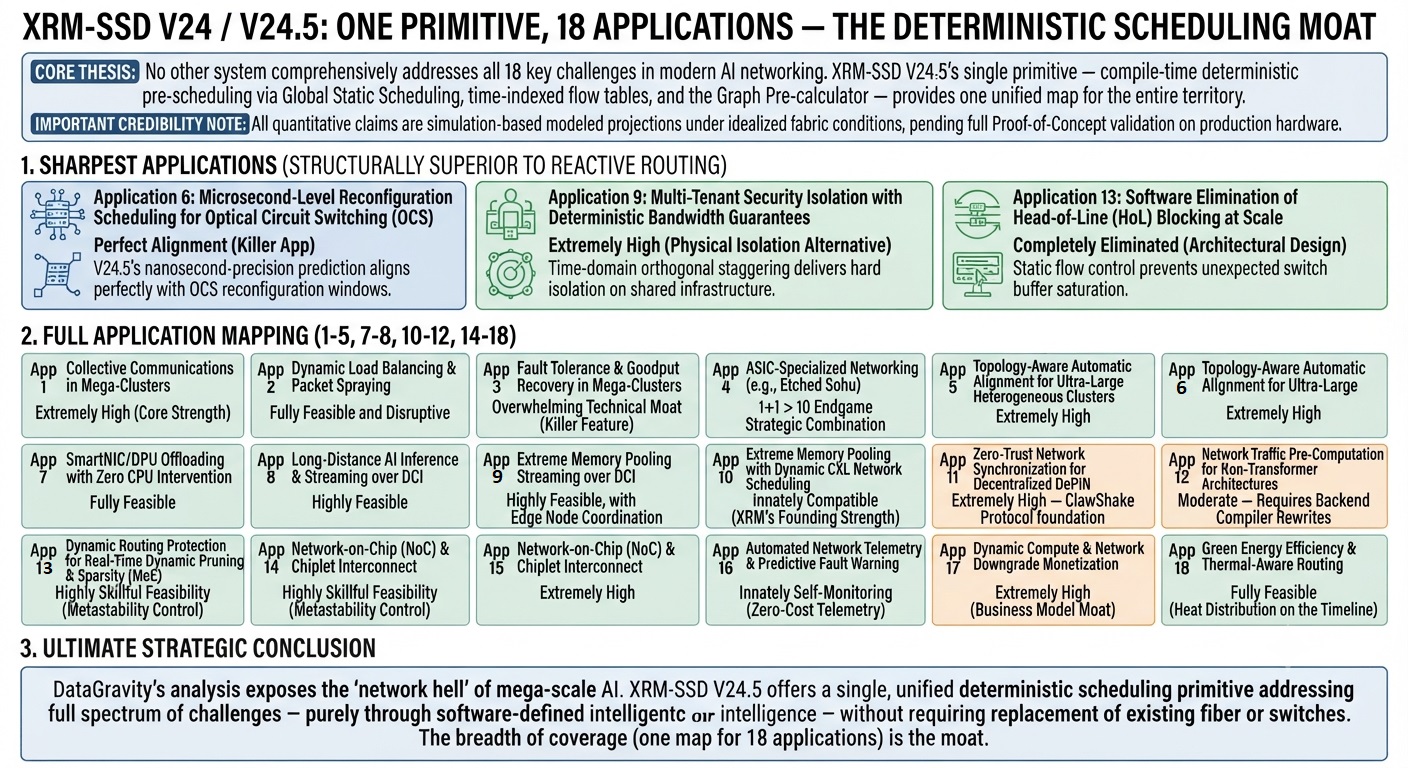
Core Thesis :
No other system comprehensively addresses all 18 key challenges in modern AI networking. XRM-SSD V24.5’s single primitive — compile-time deterministic pre-scheduling via Global Static Scheduling, time-indexed flow tables, and the Graph Pre-calculator — provides one unified map for the entire territory.
Dynamic routing stacks require separate runtime mechanisms for each problem (straggler mitigation, OCS pacing, tenant isolation, HoL blocking, etc.). One compile-time model that spans all 18 applications is the fundamental moat.
Important Credibility Note: All quantitative claims (stall reductions, utilization percentages, flip suppression rates, throughput uplifts, etc.) are simulation-based modeled projections under idealized fabric conditions. They represent expected outcomes pending full Proof-of-Concept validation on production hardware fabrics. The architectural breadth stands independently of individual point metrics.
Sharpest Applications
These demonstrate where pre-scheduling achieves outcomes that dynamic systems cannot match by design:
Application 6: Microsecond-Level Reconfiguration Scheduling for Optical Circuit Switching (OCS)
Feasibility:
V24.5’s nanosecond-precision data arrival prediction enables perfect synchronized pacing with OCS physical reconfiguration windows. Dynamic networks struggle with unpredictable packet timing, while V24.5 can pause transmission cleanly during blanks and saturate the moment paths connect.
Application 9: Multi-Tenant Security Isolation with Deterministic Bandwidth Guarantees
Feasibility: Extremely High (Physical Isolation Alternative).
Time-domain orthogonal staggering of tenant flow tables delivers hard isolation on shared infrastructure — far stronger than dynamic WRR. Ingress/egress timing is fixed at compile time.
Application 13: Software Elimination of Head-of-Line (HoL) Blocking at Scale
Feasibility: Completely Eliminated (Through Architectural Design).
Static flow control prevents unexpected switch buffer saturation. Queues remain permanently below safety thresholds by construction.
Full Application Mapping
Application 1: Collective Communications in Mega-Clusters (All-Reduce / All-to-All)
Feasibility: Extremely High (Core Strength).
Global Static Scheduling computes collision-free paths at compile time, eliminating straggler-induced stalls across 10,000+ chips. Expected to deliver major synchronization latency reductions and throughput gains.
Application 2: Dynamic Load Balancing & Packet Spraying
Feasibility: Fully Feasible and Disruptive.
Shifts complexity from runtime hardware spraying to compiler pre-calculation. Gene Fusion (χ=64 path) further reduces network traffic volume, enabling deterministic performance on standard RoCEv2.
Application 3: Fault Tolerance & Goodput Recovery in Mega-Clusters
Feasibility: Overwhelming Technical Moat (Killer Feature).
Crash Snapshot Engine + Combined protection (TMR + Invariant Checker) targets sub-millisecond recovery and high suppression of structural flips (modeled 99.8%). Enables near-instant resumption without full recompilation or long checkpoints.
Application 4: ASIC-Specialized Networking (e.g., Etched Sohu)
Feasibility: 1+1 > 10 Endgame Strategic Combination.
Zero compile overhead on fixed topologies + precise resource reclamation supports very high utilization even at massive scale.
Application 5: Topology-Aware Automatic Alignment for Ultra-Large Heterogeneous Clusters
Feasibility: Extremely High.
Graph Pre-calculator abstracts mixed hardware (H100, Blackwell, ASICs) and inserts time compensation at compile time, avoiding slowest-node stalls.
Application 7: SmartNIC/DPU Offloading with Zero CPU Intervention
Feasibility: Fully Feasible.
ResourceReclaimEngine’s proactive buffer cleaning reduces NIC cache pressure for true hardware-linear flows.
Application 8: Long-Distance AI Inference & Streaming over DCI
Feasibility: Highly Feasible, with Edge Node Coordination.
Gene Fusion compression + Crash Snapshot protection mitigates long-haul jitter and latency.
Application 10: Extreme Memory Pooling with Dynamic CXL Network Scheduling
Feasibility: Innately Compatible (XRM's Founding Strength).
Seamlessly incorporates CXL latency into the compilation matrix as a deterministic tier.
Application 11: Zero-Trust Network Synchronization for Decentralized DePIN
Feasibility: Extremely High — Core Foundation of the ClawShake Protocol.
Janibekov Mapping v2.0 + protection layers enable coherence on unreliable public networks.
Application 12: Network Traffic Pre-Computation for Non-Transformer Architectures (Mamba / RWKV / Hybrid)
Feasibility: Moderate — Requires Backend Compiler Rewrites.
Highly optimized for Transformer graphs; dynamic hidden states challenge pure static flow tables and may require partial dynamic scheduling (potential utilization impact).
Application 14: Dynamic Routing Protection for Real-Time Dynamic Pruning & Sparsity (MoE)
Feasibility: Highly Skillful Feasibility (Through Metastability Control).
χ=64 fast-path switching + Invariant Checker helps manage imbalance around expert routing. This remains one of the more demanding tests for static pre-calculation.
Application 15: Network-on-Chip (NoC) & Chiplet Interconnect
Feasibility: Extremely High (Core for Chip-Level IP Licensing).
Extends deterministic scheduling inward to chiplet-level efficiency.
Application 16: Automated Network Telemetry & Predictive Fault Warning
Feasibility: Innately Self-Monitoring (Zero-Cost Telemetry).
Timing deviation from flow tables enables precise, low-overhead fault detection and rerouting.
Application 17: Dynamic Compute & Network Downgrade Monetization
Feasibility: Extremely High (Business Model Moat).
Single-click χ=64 mode switching without restarts, preserving model quality via topology protection.
Application 18: Green Energy Efficiency & Thermal-Aware Routing
Feasibility: Fully Feasible (Heat Distribution on the Timeline).
Compiler incorporates heat models as constraints for spatial/temporal load spreading.
Ultimate Strategic Conclusion
DataGravity’s analysis exposes the “network hell” of mega-scale AI. XRM-SSD V24.5 offers a single, unified deterministic scheduling primitive capable of addressing the full spectrum of challenges — purely through software-defined intelligence and topology protection — without requiring replacement of existing fiber or switches.