Home ﹥ Hot News > Artificial Intelligence > Computing > Token Economics 2026-08-15
Links:https://fortune.com/2026/08/13/anthropic-said-in-talks-to-bu ...
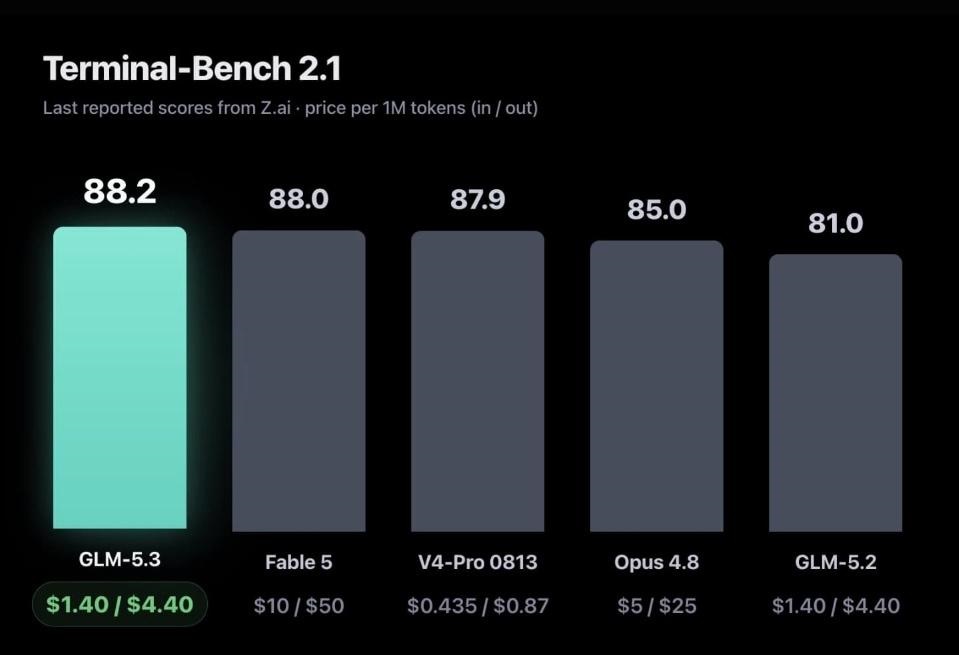
If the Terminal-Bench 2.1 numbers in this chart hold roughly true over the next two years, and if Fable 5 / Opus 4.8's token costs see almost no improvement, then the problem becomes very serious.
The current gap from your chart is:
Model Score Input / 1M Output / 1M Relative to GLM-5.3 Output
GLM-5.3 88.2 $1.40 $4.40 1 ×
Fable 5 88.0 $10 $50 11.4×
V4-Pro 0813 87.9 $0.435 $0.87 0.20×
Opus4.8 85.0 $5 $25 5.7×
GLM-5.2 81.0 $1.40 $4.40 1×
In other words, Fable 5 has nearly the same score, but its output cost is 11.4× that of GLM-5.3. Opus 4.8 is even 3.2 points lower, yet still costs 5.7× more.
This isn't just a "pricing issue"—it gradually becomes an Inference Economics problem.
Phase 1: Enterprises shift to "cost per task"
If Fable/Opus only improve intelligence over the next two years without reducing reasoning tokens, output tokens, or inference cost, companies will stop looking at:
"Which model has the higher benchmark score?"
and start asking:
"Which model costs the least to complete the same task?"
This trend is already emerging. Studies show that cheaper-labeled reasoning models can sometimes have higher per-task costs because thinking-token consumption varies dramatically.
Thus, the real KPI becomes:
Cost / solved task
not:
$/1M tokens
Phase 2: Fable 5 / Opus 4.8 will be forced to cut prices
Suppose two years from now:
· Fable 5 = $10 / $50 — still unchanged
· Competitors gradually drop to: $1 / $4
Then Fable's output premium becomes:
12.5×
If intelligence is only 5–10% ahead, that premium is very hard to sustain.
In fact, the market in 2026 is already showing intense pricing pressure: OpenAI recently slashed prices on several models, and Chinese models continue to push costs down.
More extreme: DeepSeek V4-Flash has already pushed input/output to $0.14 / $0.28 per 1M tokens.
So the real point worth noting in your chart isn't 88.2 vs 88.0.
It's:
88.2 @ $4.40 vs 88.0 @ $50
That is a very dangerous economics ratio.
Phase 3: The model market starts to "stratify"
I think the most likely outcome in two years isn't Fable/Opus disappearing, but the market splitting into:
Tier 1 — Ultra-cheap / high-volume
GLM / DeepSeek / Qwen / open-weight models
→ Bulk routine work
→ Agent background tasks
→ Coding sub-tasks
→ Summarization
→ Classification
→ Routing
Tier 2 — Premium reasoning
Fable / Opus / GPT-class
→ Truly hard reasoning
→ High-value coding
→ Research
→ Critical decisions
In other words:
Cheap models become the workforce.
Premium models become the specialists.
This is actually more likely than "cheap models completely replace Opus."
Phase 4: The biggest threat is actually the "Router"
This is highly relevant to what you're doing with XRM Brain-X / router_service.
Suppose a business has 100 tasks:
100 tasks
│
├── 70 simple
│ └── GLM / DeepSeek / cheap model
│
├── 25 medium
│ └── mid-tier model
│
└── 5 extremely difficult
└── Fable / Opus
There's no reason for the business to send:
100/100 requests → Opus
Instead, it becomes:
95/100 → cheap models
5/100 → premium model
This directly reduces Opus/Fable's token volume.
So the real competition isn't:
"Who has the strongest model?"
It's gradually becoming:
"Who can route tasks to a good-enough model at the lowest cost?"
This is precisely the value of intelligent routing.
Phase 5: Worst-case scenario if nothing improves in two years
Assume by 2028:
Fable
· Benchmark: 88 → 92
· But: $10 / $50 → $10 / $50
Competitors
· Benchmark: 88 → 91
· Price: $1.4 / $4.4 → $0.5 / $2
Then Fable's problem isn't "performance lag."
It's:
Performance advantage / Cost disadvantage
becoming an extremely poor ratio.
Enterprises will ask:
"Why should I pay 10–25× the inference cost for only a few percentage points of benchmark improvement?"
This creates enormous pricing pressure.
Phase 6: Opus's situation is somewhat different
Opus 4.8 at:
85 @ 25
is in a more dangerous position than Fable, because in your chart:
GLM-5.3 = 88.2
already has:
Higher performance + Lower cost
If this benchmark holds across different workloads, prompts, batches, and concurrency levels, Opus's commercial positioning must change.
It may survive only on:
· Higher reliability
· Stronger agent capability
· Better coding
· Longer context
· Lower hallucination
· Enterprise security
· SLA
· Tool-use
· Ecosystem
to maintain its premium.
Phase 7: The most important shift — Tokens themselves may become an "obsolete KPI"
I think this is especially important for your XRM Brain-X
The future cost formula will look closer to:
C_task = T_input·P_i + T_output·P_o + T_reasoning·P_r + C_memory + C_routing + C_retry
rather than:
C = Tokens × Price
Because for the same 1M tokens:
Model A might complete it in one pass
Model B might do:
· reasoning
· tool call
· retry
· correction
· second reasoning
· final
and end up spending 3–5× more tokens.
Research already shows that thinking-token consumption can drastically alter actual task cost.
Phase 8: An important signal for XRM Brain-X
If Fast/Slow Cascade + uncertainty router can do:
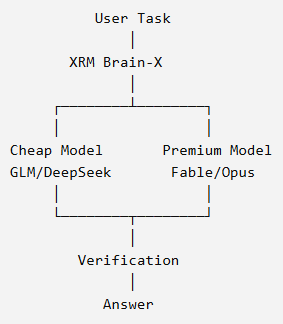
Then it's not just "model selection."
It's doing:
Cost-aware intelligence allocation
For example:
· 95% of tasks use $1–4/M token models
· 5% of tasks use $25–50/M token models
If accuracy remains essentially unchanged, enterprises won't see:
"XRM is 20% faster."
They'll see:
"The total inference bill for the same AI workload dropped 60–90%."
That business value is far greater than a benchmark +2%.
---
My two-year judgment
If Fable 5 / Opus 4.8 really can't improve token economics over two years:
Most likely:
Premium → Specialized Premium
rather than outright disappearance.
Medium-term:
Cheap models capture massive volume
After that:
Router / orchestration layer decides who gets premium inference
Finally:
Models themselves gradually commoditize. What truly holds value is: "How much intelligence is used per task, on which model, when to upgrade, when to stop reasoning."
The market is already moving in this direction: token prices continue to drop rapidly on one side, while frontier reasoning still commands a high premium. A 2026 pricing study even estimated that budget/mid-tier models are seeing price declines faster than traditional Moore's Law, while flagship reasoning models show significantly slower price drops.
It's more like showing a potential industry inflection point:
88.2 points at $4.40/M may be closer to the future economic model of AI infrastructure than 88.0 points at $50/M.
This is also why, if XRM Brain-X can unify routing, KV/context management, early-exit, verification, and model selection into a cost-aware orchestration layer, its value may not come from "building another 90-point model," but from helping enterprises buy 5–10× less expensive inference.